 IN-V-BAT-AI
MATH TEST AI TUTOR 💖 Only $ 1
IN-V-BAT-AI
 The three most important challenges in AI inference are:
 (1) latency under high concurrency,
 (2) memory and KV‑cache bottlenecks, and
 (3) cost‑efficient scaling under unpredictable workloads.
KV means Key–Value. During inference — the moment an AI is answering a question or reviewing code — the Transformer inside the GPU builds a memory called the KV‑cache. It stores a Key (K), which represents the topic or “what this token is about,” and a Value (V), which represents the contextual meaning connected to that token. The GPU converts these words into numerical vectors that computers can process. These vectors are not simple binary, octal, or hexadecimal numbers — they are high‑dimensional floating‑point numbers — but you can think of them as the computer’s numerical language. This word‑to‑token conversion happens extremely fast and repeats for every token the AI generates.
Simple version

KV means Key–Value. When an AI is answering, it stores a Key (the topic of each word) and a Value (the meaning connected to that word). The GPU turns every word into numbers so it can think fast. This happens for every token, many times per second, and the stored Keys and Values form the AI’s short‑term memory during inference.
🔧 1. Latency & Concurrency Pressure

AI inference must respond in real time, often serving thousands or millions of simultaneous requests. Unlike training—which is throughput‑oriented—inference is latency‑sensitive and concurrency‑heavy, requiring extremely fast time‑to‑first‑token and efficient autoscaling. Real‑time workloads are bursty, making traffic management and routing essential.

🧠 2. Memory Bottlenecks & KV‑Cache Growth

Modern large language models are memory‑bound during inference, not compute‑bound. Long‑context inference rapidly expands the KV‑cache, consuming GPU memory and limiting how many requests can run concurrently. This leads to slowdowns, higher latency, and underutilized compute. Research highlights that memory and interconnect bandwidth—not raw compute—are now the dominant constraints for LLM inference.

📏 3. Cost‑Efficient Scaling & Resource Management

Inference costs scale with usage, not training duration. Because workloads are unpredictable, organizations risk over‑provisioning (wasted spend) or under‑provisioning (slow responses). Inference also requires efficient checkpoint loading, memory‑optimized serving, and hardware‑aware optimizations to keep cost per request low.
💡 Compare and Contrast the Inference Challenges of IN-V-BAT-AI to Other Leading AI Companies

IN‑V‑BAT‑AI faces fundamentally different inference challenges than hyperscalers like Google, Nvidia‑aligned cloud providers, or national AI programs.

The key contrast: IN‑V‑BAT‑AI optimizes for deterministic, low‑compute, classroom‑grade inference, while leading AI companies optimize for massive‑scale, high‑throughput, multimodal inference under extreme hardware constraints.
🔧 1. Why IN‑V‑BAT‑AI’s Challenges Are Strategically Easier to Solve


Because IN-V-BAT-AI:

avoids GPU scarcity entirely (a major national‑level bottleneck). Has no hardware dependency  (HTML/JS deterministic engines)
avoids KV‑cache memory blowups. Very low; no KV‑cache explosion problem.
avoids multimodal inference complexity. Uses deterministic reasoning with minimal compute.

🌐  2. Strategic Insight

IN-V-BAT-AI platform’s inference challenge is not “how to serve 10M QPS,” but how to guarantee perfect reasoning clarity, instant load, and deterministic steps—a fundamentally different optimization problem than Google, Nvidia, or national AI programs.

✨  2. Why IN‑V‑BAT‑AI still scales to 10,000,000 students

Because IN‑V‑BAT‑AI generators are static HTML, static JS, static CSS, and static PNG assets, they are automatically cached (other word for saving) in each student's  smartphone or tablet web browser, allowing them to load instantly with minimal IN-V-BAT-AI server demand.
Here’s a concrete, intuitive example that shows exactly what I mean when I say:

“These vectors are not simple binary, octal, or hexadecimal numbers — they are high‑dimensional floating‑point numbers — but you can think of them as the computer’s numerical language.”
✅  A Real Example: How a Single Word Becomes a Vector

Let’s take the word:

“cat”

A computer cannot store “cat” as:
- binary like `01100011 for letter c;  01100001 for letter a; 01110100 for letter t`
- octal like `143 for c; 141 for a;  164 for t`
- hexadecimal like `63 for c;  61 for a;  74 for t`

Those are just text encodings, not meaning.

A Transformer needs meaning, so it converts “cat” into a vector — a long list of floating‑point numbers.

Here is a simplified example (real vectors are 1,024 counts to 4,096 counts long):

cat → [0.12, -0.88, 0.03, 1.44, -0.55, 0.91, up to 1,024 counts]

cat → [0.12, -0.88, 0.03, 1.44, -0.55, 0.91, up to 4,096 counts]

Each number is:
- not binary
- not octal
- not hexadecimal
- but a floating‑point number like 0.12 or -0.88

This list of numbers is the computer’s internal language of meaning.
🧠 Why these vector numbers matter

The vector for “cat” ends up *close* to vectors for:

"kitten" → [0.10, -0.90, 0.05, 1.40, -0.50, 0.93, ...]

"dog"    → [0.11, -0.85, 0.02, 1.42, -0.53, 0.89, ...]

But far away from:

"airplane" → [-2.55, 0.33, -1.44, 0.02, 3.10, -0.77, ...]

AI models understand similarity by measuring the distance between vectors. One common way to compute this distance is the Radial Basis Function (RBF) kernel or another term for mathematical equation, a mathematical formula widely used in machine learning.

AI Causal Inference Webinar
🔗 Now connect this to KV‑cache

During inference:

- Key (K) = “What is this token about?”

Example: about the heading or subject “cat” → a vector like `[0.12, -0.88, 0.03, ...]`

- Value (V) = “What meaning or context does this token carry?”

related to its "kitten" → [0.10, -0.90, 0.05, 1.40, -0.50, 0.93, ...]

The GPU stores these vectors in the KV‑cache so the model can reuse them instead of recomputing them.

This is why the KV‑cache grows with every token — each token adds two long vectors (K and V) for every layer and every head meaning heading or subject.

🎯 Your metaphor still works

Even though the real numbers are floating‑point values like:

0.12, -0.88, 1.44, -0.55

…you can still teach students:

“The computer turns words into its own numerical language — like advanced versions of binary, octal, or hex — so it can think fast.”

That keeps the metaphor without sacrificing accuracy.
What a floating‑point element actually looks like inside those long AI vectors.

Here’s the clean, accurate answer:

✅ How many digits does each floating‑point number have?

A floating‑point element in an AI vector is typically stored in one of these formats:

1. FP32 (32‑bit float)
Looks like:

0.12345678

-1.004392

3.1415927

- Usually 6–8 decimal digits of precision
- Stored using 32 bits inside the GPU

2. FP16 (16‑bit float)
Looks like:

0.12

-1.00

3.14

- Usually 3–4 decimal digits of precision
- Stored using 16 bits
- Very common in inference because it saves memory

3. BF16 (bfloat16)
Looks like FP16 but with better range:

0.123

-0.998

2.718

- 3–4 decimal digits
- Used heavily in training and inference on TPUs/GPUs

4. INT8 / FP8 (quantized)
Looks like:

0.11

-0.87

1.44

- 1–2 decimal digits
- Used for ultra‑fast inference
- Saves huge amounts of memory
🔍 So how many digits do you *see* in a vector?

When you print a vector from a model, you typically see something like:

[0.1234, -0.8892, 1.4421, -0.5520, 0.9103, ...]

Each element is usually 4–8 digits long, depending on the precision.

But inside the GPU, the number is stored in binary floating‑point format — not decimal digits — so the “digits” you see are just a human‑friendly representation.

🧠 Why this matters for AI inference

Every token produces:
- a Key vector
- a Value vector
- across every layer
- across every attention head

Each vector contains hundreds or thousands of these floating‑point numbers.

That’s why the KV‑cache explodes in size — even though each number is only a few bytes, the *multiplication* across layers × heads × tokens × batch size becomes massive.

🎯 Quick summary

Each floating‑point element in an AI vector is usually 4–8 digits long when printed, but internally it’s stored as a 16‑bit or 32‑bit floating‑point number. These numbers form the AI’s internal numerical language for meaning.
If my GPU is configured to INT8 / FP8 (quantized). Tell me the number of counts of long vector for cat.

Short answer: INT8 / FP8 changes the *precision* of each number, not the *count* of numbers in the vector.
The number of elements in the “long vector for `cat`” is set by the model’s hidden size, not by quantization.

 1. What “count of long vector” really means for a token like `cat`, the model creates a
 vector of length \(d\):

[ \text{cat} \rightarrow [x_1, x_2, x_3, \dots, x_d]

- \(d\) is the embedding / hidden dimension.

- Typical values (depends on the model, examples):

- the word 'cat' in Small model: 512 vector counts or 768 counts

“Vector element,” “vector count,” “vector number,” and “vector dimension” all mean the same thing — they tell you how many numbers are inside the vector.
Simple 3D vector diagram
Our eyes and brain can understand and interpret easily up to 3 dimension.
Now imagine using small SLM(Small Language Model). The word 'cat' is pre-assigned with 512 dimensions during training.(Trade secrets of frontier labs)
Our eyes struggle to visualize 512 mathematical dimensions — the human visual system is built for only three.
But the brain has no such limitation: neurons routinely operate in spaces with thousands of dimensions, and representing 512‑dimensional patterns is effortless for neural circuits.
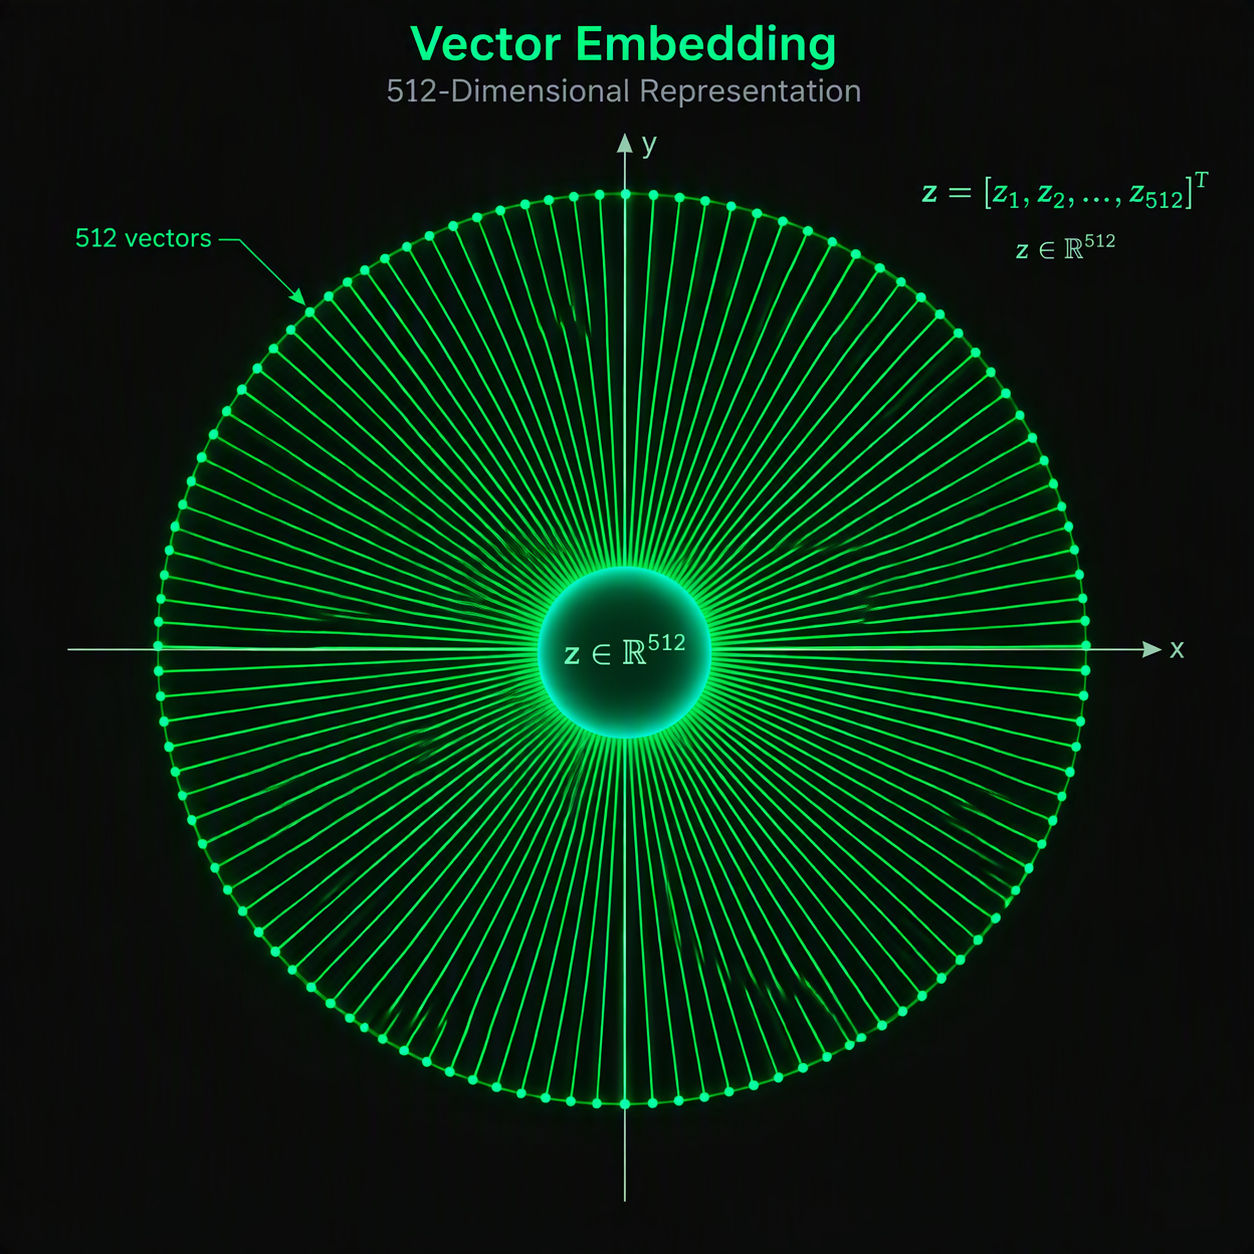
KV cache: K - Key is pre-assigned to topic like cat the center.
V - Value is pre-assigned to context associated to the topic cat. In this example the value or context is 512 dimension or relationship context.
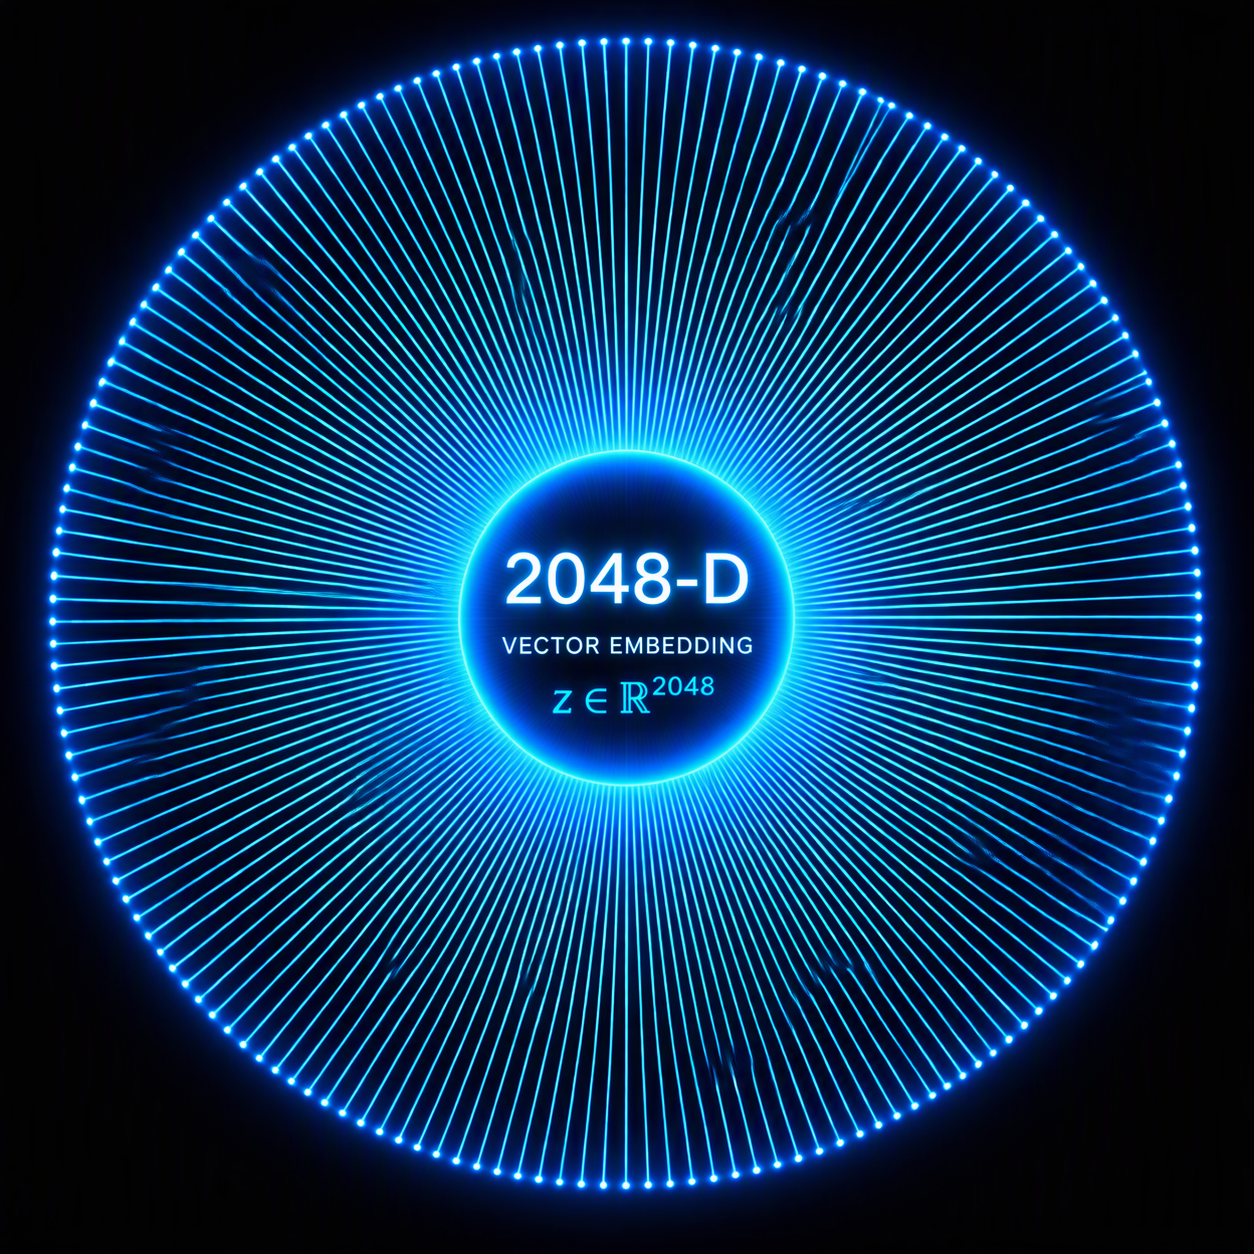
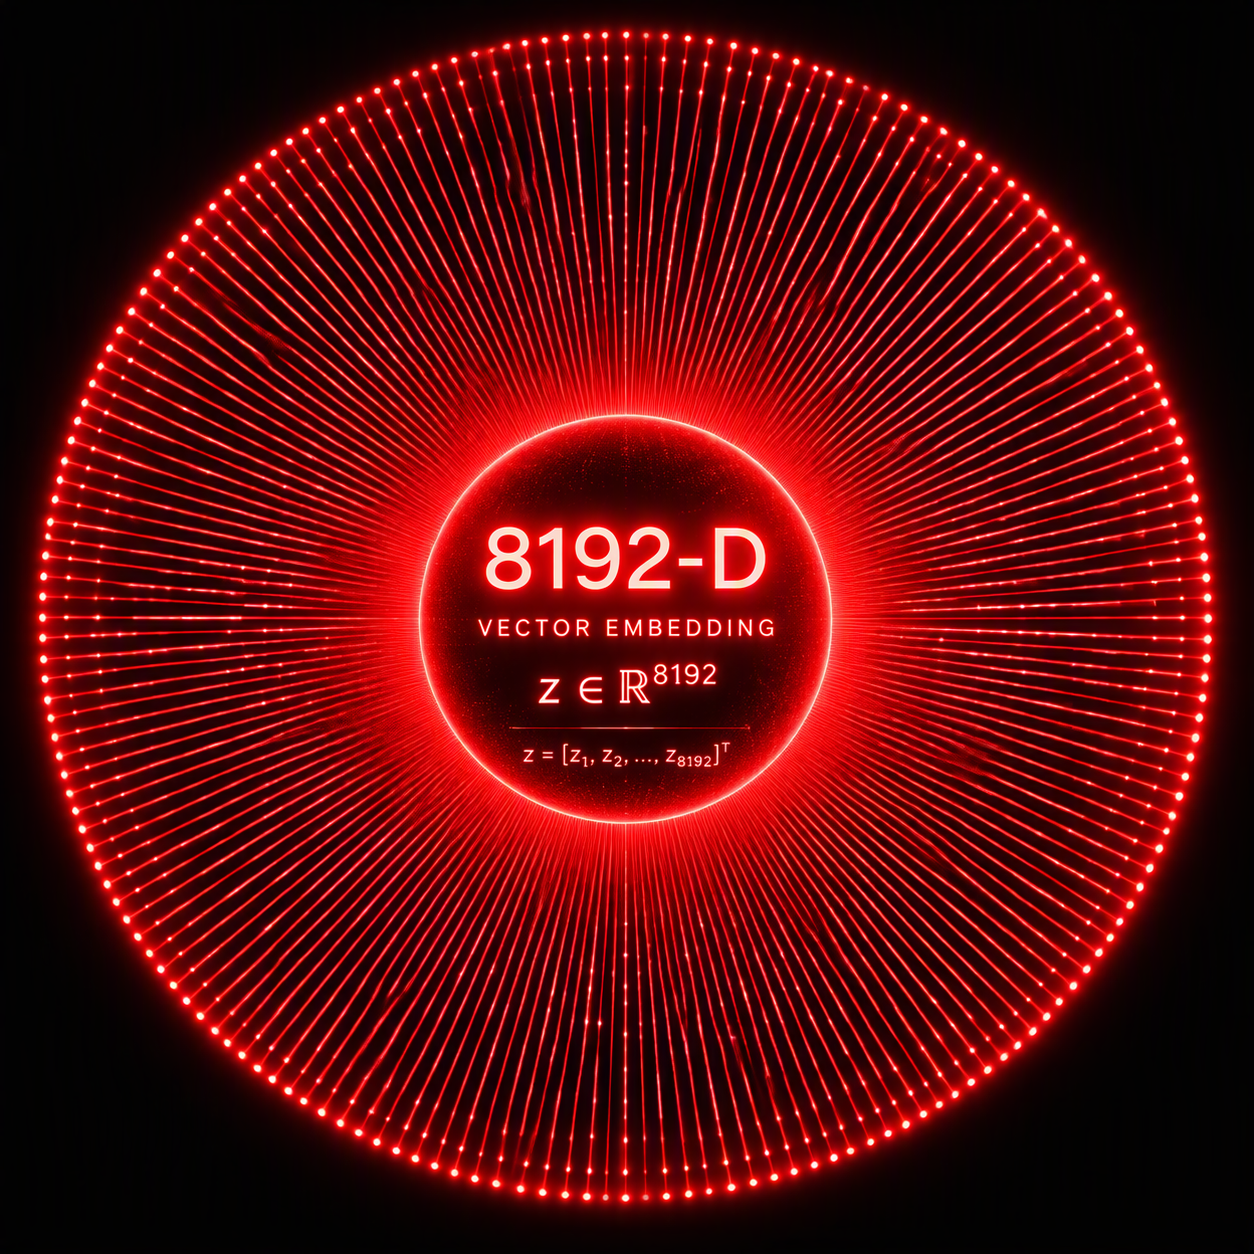
So the “count” is usually hundreds to thousands of numbers *per vector per token*.

What INT8 / FP8 changes

With INT8 / FP8, each element in that vector:

- still exists (same count: 512, 1024, 4096, etc.)
- but is stored with fewer bits:
  - FP32: 32 bits per element
  - FP16/BF16: 16 bits per element
  - INT8 / FP8: 8 bits per element

So if your model has, say, 4096‑dimensional vectors, then:

- `cat` → 4096 numbers
- in FP32: 4096 stored by 4 bytes (remember 8 bits = 1 byte; 8 bits x 4 = 32 bits)
- in INT8 / FP8: 4096 stored by 1 byte (8 bits)

The count stays 4096; only the size per element shrinks.

You could say:

“For each token like `cat`, the model creates a long vector with thousands of numbers (for example, 4,096). Quantization to INT8 or FP8 does not change how many numbers are in that vector—it only makes each number smaller in memory, so the GPU can store more tokens in its KV‑cache.”
 2 •
 3 •
 4 •
 5 •
 6 •
 7 •
 8 •
 9 •
 10 •
 11 •
 12 •
 13 •
 14 •
 15 •
 16 •
 17 •
 18 • 5 sec
 Tap for link